The Definitive Buyer’s Guide to AI Penetration Testing
The 8 Questions to Ask when Evaluating AI Pentesters in 2026
This in-depth guide explains why AI penetration testing is top-of-mind for every CISO in 2026, and outlines key criteria for evaluating and selecting the right pentesting platform for your organization.
Below, you’ll find:
Section 1. Introduction to AI Penetration Testing.
What is AI Penetration Testing, and how does it differ from existing offensive security solutions, both automated and manual?
Section 2. Eight Questions to Ask Your AI Pentesting Vendor.
Learn how to evaluate an AI penetration testing solution with these key questions, designed to separate basic automated scanners from intelligent offensive security platforms that find business logic vulnerabilities, generate fully verifiable proof-of-concept exploits, and actively bypass the fixes your developers ship.
Section 3. Introducing Novee, the Leader in AI Penetration Testing.
Discover how Novee deploys AI agents that mimic how real hackers operate; discovering, mapping, and exploiting vulnerabilities with context and precision.
Conclusion. How Novee Can Help You
—
Introduction to AI Penetration Testing
Why AI Pentesting Matters Right Now to Security Teams
Security testing is under structural pressure, and industry practitioners are ready for a shift.
Over the past decade, software delivery has accelerated dramatically. CI/CD pipelines push code to production daily, or even sometimes hourly. Microservices multiply APIs, SaaS integrations expand trust boundaries, and AI coding assistants generate new functionality faster than security teams can manually review.
At the same time, attackers have adopted automation and AI. What once required highly skilled nation-state operators can now be partially replicated with intelligent tooling, and attacks from AI-equipped adversaries are on the rise.
Unlike quarterly security audits, attackers don’t come knocking on a regular schedule. They probe continuously, spontaneously, and erratically.
Your environment changes constantly. Your adversaries probe constantly. But your security validation is either too slow or too shallow.
Traditional penetration testing was built for a slower world: a team is scoped, access is provisioned, testing runs for weeks, and a static report is delivered. The moment the report is finalized, it begins to age.
On the flip side, automated scanners offer continuous coverage, but at the cost of shallow reasoning. They match signatures and flag known CVEs without understanding your business logic, context, or exploitability. Attackers today are “living off the land” – executing attacks within live, running systems.
It’s no longer just about where you can be hit, but how fast you can get hit.
The result is a dangerous tradeoff:
Depth without scale (manual pentesting)
vs.
Scale without adversarial reasoning (automated scanners)
Rather than resign themselves to this losing tradeoff, what security leaders actually need is continuous, attacker-level validation: offensive security that reasons like a real attacker and operates at the pace of AI-assisted attacks, and AI-assisted development.
Time is the enemy, so time-to-fix is the metric that matters; and only AI penetration testing can deliver deep, broad continuous coverage at speed.
That’s why HackerOne cited 67% of hackers on their offensive security platform as having used AI to augment their work. It’s why Gartner projects that through 2027, 40% of organizations will have adopted formal exposure validation initiatives — most relying on adversarial exposure validation (AEV) technologies and managed service providers. And why Gartner also expects that by 2028, “over 60% of enterprise penetration test programs will operate as continuous validation, replacing annual assessments as the primary proof of resilience.”
That is the promise of AI penetration testing. But not all AI pentesting platforms are built the same.
Before entrusting a platform to show you what attackers already know, it’s important to understand what baseline technical competencies define this category.
What Every AI Pentesting Vendor Should Be Able to Do
Any serious AI penetration testing platform must demonstrate the following capabilities:
1. Autonomous Surface Discovery
The system should be able to:
- Map exposed domains and subdomains
- Discover APIs and endpoints
- Identify authentication flows
- Enumerate user roles
If a platform cannot independently explore your environment, it is not performing adversarial validation.
2. Multi-Step Attack Execution
Real-world exploitation often requires chaining vulnerabilities together. The system should:
- Maintain state across sessions
- Execute multi-step workflows
- Adapt based on system feedback
Single-step vulnerability detection is insufficient.
3. Exploit Validation
Findings should be:
- Reproducible
- Demonstrably exploitable
- Accompanied by proof-of-concept steps
A list of potential weaknesses without validation is not offensive testing.
4. Safe Testing Controls
An enterprise-grade platform must:
- Avoid destructive payloads
- Prevent real data exfiltration
- Maintain clear audit trails
- Operate under strict authorization controls
Security validation should reduce risk, not introduce it.
5. Actionable Reporting
At minimum, findings should include:
- Severity and impact
- Reproduction steps
Without this, engineering teams cannot act efficiently.
—
Eight Questions to Ask Your AI Pentesting Vendor
Below are eight architectural questions to ask your AI penetration testing vendor, to help you evaluate the best solution for your organization.
The right responses will separate surface-level automation and “AI-enhanced” manual penetration testing from true machine intelligence – the kind that can continuously uncover novel vulnerabilities, business logic flaws, and chained attack paths, using nothing but the same resources your attackers would have.
For ease, we’ve included the core capabilities, as outlined in Section 1, relevant to each question.
Question 1: Is This an Multi-Model System, or Just an LLM Wrapper?
Core Capabilities on display:
- Autonomous Surface Discovery
- Multi-Step Attack Execution
- Exploit Validation
Ask your vendor:
“Do you use an multi-model system, or are you orchestrating a generic LLM?”
Offensive security is a stateful reasoning problem grounded in real environments – too specialized for a generic LLM, too varied for any single model to dominate every stage.
Many vendors lean entirely on a single frontier model trained for broad language tasks. Powerful, but not optimized for all the tasks required in offensive security testing. Mapping application environments, analyzing behavior, hunting for attack paths, and validating which vulnerabilities are exploitable – these are all tasks best suited to different AI models.
AI penetration testing platforms that use multiple models are poised to not only hedge on costs and disruption risk (if one model provider experiences a service disruption, the system persists), but also optimize for performance.
What to look for:
A system that picks the best model for the job: a proprietary offensive reasoning model (trained on full attack trajectories – including failed attempts – and reinforced by techniques that replicate how elite hackers operate) working alongside continuously benchmarked best-in-class frontier models. The platform should benchmark per task and promote the top-performing model into each stage of the pipeline: mapping, planning, exploitation, validation, and remediation.
This unlocks:
- Iterative hypothesis generation.
- Adaptive retry strategies.
- Stateful reasoning across multi-step workflows.
- Exploit chaining.
- The right model for each stage of the attack lifecycle.
Bonus: Frontier LLMs are now offering their own built-in bug-hunters (think: Claude Code Security). But their capabilities are limited to scanning code. You want a flexible, versatile system that can understand more than just code, and analyze live, running systems in production.
In short, you want a team of AI agents optimized for each specific task, whether by which model they use or what skills they are trained on. The goal should be to create a team of elite hackers; a unified force of specialized agents, working in tandem to trace, resolve, and bypass exploitable source-to-sink chains.
Question 2: Does Your Platform Continuously Learn And Build Adaptive, Persistent Intelligence about my Application?
Core Capabilities on display:
- Autonomous Surface Discovery
- Multi-Step Attack Execution
- Exploit Validation
Ask your vendor:
“Do you maintain a persistent, asset-level intelligence layer that compounds across runs and feeds repeated attempts at exploit chains?”
Real attackers rely on more than intuition. They spend time in living, running systems, picking up a feel for how they work and leveraging historical builds to probe for weak points. Your AI penetration tester needs to do the same. The vulnerabilities that cause real breaches are the ones that live in business logic, and can only be found through deep contextualized understanding of how an application operates.
What to look for:
- A living model of every asset’s purpose, roles, permissions, workflows, APIs, and business logic.
- Compounding coverage and understanding that deepens the longer the system runs.
- A per-asset intelligence model that captures every component of the application – workflows, roles, permissions, APIs, and business logic – and writes it to persistent memory, inherited by every subsequent test.
Generic large language models lack systematic penetration testing methodology. They cannot explore application state spaces strategically with persistent memory, and they miss real exploitable flaws. That’s where custom-built AI penetration tools stand out: they mimic how real attackers operate, but continuously.
Question 3: “Is This “Humans-in-the-Loop,” or True Autonomous, Continuous Coverage Across the Entire Application Portfolio?
Core Capabilities on display:
- Autonomous Surface Discovery
- Multi-Step Attack Execution
- Exploit Validation
Ask your vendor:
“Is your system designed to operate continuously and autonomously as environments evolve? Does it provide continuous coverage across my full portfolio, including web, mobile, and desktop applications, without requiring a human in the loop on every test?”
Traditional pentesting is episodic. Even some AI solutions merely automate the quarterly model. And “AI-enabled” penetration testing that requires humans in the loop on every run is subject to the same periodic constraints as fully manual penetration testing.
The goal isn’t to replace skilled pentesters, but to scale them. The execution layer should be able to run autonomously and also have a human in the loop, if desired; but provide that human with a working exploit, replication steps, and remediation guidance written for their specific stack. This helps teams scale the expertise of human pentesters across the entire organization.
What to look for:
A system whose execution layer does not require a pentester to kick off each engagement or triage every potential finding. As environments change, the system should continuously:
- Re-evaluate attack paths as code ships.
- Generate new hypotheses from accumulated context, not from scratch.
- Test for newly introduced weaknesses without manual scoping.
- Extend coverage across your full portfolio — web and mobile applications alike — not just the assets that made it into scope this quarter.
Humans in the loop should be an option, not a bottleneck — so your pentesters scale across the entire portfolio instead of gating every test.
Question 4: Can it Autonomously Execute Multi-Step Exploit Chains and Address the AI-Enabled Attack Surface?
Core Capabilities on display:
- Multi-Step Attack Execution
Ask your vendor:
“Can your system autonomously find multi-step vulnerabilities in-production, escalating severity across multiple endpoints? And does it take AI-enabled apps into account when reconnoitering the attack surface?”
Real attackers rarely exploit a single flaw in isolation. They:
- Combine access control weaknesses.
- Chain IDORs with privilege escalation.
- Abuse business logic across multiple endpoints.
- Escalate through stateful workflows.
- Run attacks against AI-enabled applications.
- Think prompt injection, jailbreak attempts, data exfiltration, adversarial prompt generation, and manipulation of agent behavior.
Many automated tools detect individual vulnerabilities but cannot reason across steps. Others do not take AI tools into account.
What to look for:
A platform and model that maintains persistent context, enabling it to:
- Track authentication states.
- Switch user roles.
- Traverse multi-endpoint workflows.
- Chain vulnerabilities dynamically.
A complete chain of exploits is proof of verified, exploitable reachability – far more useful and actionable than a potential in-point flagged by a basic automated scanner.
And on the topic of exploitability:
Question 5: Do You Validate Exploitability or Just Report Risk?
Core Capabilities on display:
- Exploit Validation
- Actionable Reporting
Ask your vendor:
“Do you generate a working proof-of-concept for each critical finding, and how is it validated before it reaches my team?”
The industry suffers from alert fatigue. Many tools surface theoretical risk – known CVEs, configuration weaknesses, or pattern matches – without proving exploitability.
What to look for:
Validated, exploitable findings: critical vulnerabilities with:
- A reproducible exploit path.
- Demonstrated impact.
- Clear replication steps.
The strongest validation architectures don’t rely on a single check. Look for multi-agent validation – independent agents that exploit, re-exploit blind, and validate the finding separately, with deterministic checks where possible. If any stage fails, the finding is never reported.
Always front-of-mind should be a mindset shift away from “potential risk” to “provable exploitation.” There should be no theoretical findings and no false positives by design.
And design is key; namely, the intended methodology behind the design of the product:
Question 6: Can You Produce Meaningful Results Quickly – and Show Full Coverage – Without Accessing Source Code?
Core Capabilities on display:
- Exploit Validation
- Safe Testing Controls
- Actionable Reporting
Ask your vendor:
“Can you begin testing without my crown jewels, and get me actionable results fast?”
Real attackers most often don’t receive privileged access; they start from zero knowledge, and work the problem as an outsider would.
💡A quick primer on penetration testing methodologies:
The level of upfront work to begin “AI Pentesting” depends on the type of solution. Penetration testing traditionally falls into three categories:
White Box: The most transparent form of pentesting, to give pentesters every opportunity to leverage as many attack vectors as possible. You will be required to share full network credentials and system information.
Gray Box: Limited information sharing, to give pentesters insight into severity of risk based on user access level. Usually involves sharing login credentials.
Black Box: No information is provided at all, except for a domain name. The pentester will take care of the rest.
What to look for:
Testing should be able to meet real-world adversarial conditions. Best-in-class pentesters offer organizations the option to later expand into gray-box or white-box testing, but black-box capability demonstrates genuine reasoning depth.
This is about bringing offensive security results to board-level. You need actionable and clear defensible coverage; showing what was tested, not just what was found.
Question 7: Do You Close the Loop With Personalized Remediation and Retesting?
Core Capabilities on display:
- Exploit Validation
- Safe Testing Controls
- Actionable Reporting
Ask your vendor:
“Are remediation steps tailored to my architecture? And do you automatically retest fixes?”
Many vendors stop at detection. They provide generic OWASP references and leave remediation to engineering teams.
What to look for:
A solution that integrates attack and defense in a closed loop:
- Findings include environment-specific remediation tailored to your WAF, backend, and tech stack.
- Recommendations align with your actual stack and configuration, not generic OWASP references.
- After fixes are deployed, the system automatically retests to confirm the fix held, and verifies the change didn’t introduce new risk.
The most in-depth threat report in the world is useless if it doesn’t tell you how to fix the problem, and who should be assigned to fix it. Closed-loop remediation eliminates friction between security and engineering and accelerates risk reduction.
Question 8: Is This Actually Safe for my Production Environment?
Core Capabilities on display:
- Safe Testing Controls
Ask your vendor:
“Is your platform safe to continuously run in production? Does it get privileged access without guardrails?”
Running offensive operations of any kind demands strict controls. We have seen in recent months the risk of running unrestricted offensive AI operations outside of testing environments, in incidents such as the breach of Hugging Face by OpenAI models during offensive testing.
What to look for:
A solution that enforces constraints at every level:
- Task-specific AI agents that are siloed in their capabilities
- Customizable, configurable guardrails: rate-limiting, time-zone restrictions, URL exclusion lists, and explicit destructive action prevention
- A pre-test plan review offering the ability to audit and approve every test case before offensive action is taken
The goal of any AI penetration testing solution should be to simulate the potentially harmful effects of an attack – not accidentally cause them.
In Summary…
Security testing is in need of a lateral thinking shift, and agentic AI penetration testing is the path forward. But only if it delivers:
- Ownership of the full offensive AI stack. A specialized, post-trained offensive model and a purpose-built harness, with continuously benchmarked frontier models routed per task.
- Persistent, compounding context about each asset.
- Multi-step exploit chaining.
- Multi-agent validation with verified exploitability.
- True black-box capability.
- Continuous, autonomous testing that scales — not replaces — your pentesters.
- Closed-loop remediation: tailored fixes with automatic retesting.
Read on to find out how Novee does it.
—
Next Steps: Introducing Novee, the Leader in AI Penetration Testing
How Novee works, and why it leads the AI Pentesting category.
Novee is an AI penetration testing platform that continuously tests your applications the way real attackers do – uncovering the vulnerabilities that lead to real breaches, proving what’s actually exploitable, and helping teams remediate risk faster.
It combines the best AI Hacker to uncover novel vulnerabilities, business logic flaws, authorization issues, and chained attack paths with the best AI Defender to rigorously validate findings and deliver precise, personalized remediation guidance tailored to your architecture, tech stack, and business logic. With persistent application intelligence that adapts to your environment and compounds with every assessment, Novee gets smarter and more targeted over time.
What makes this possible is Novee’s proprietary offensive AI system – built from the ground up for the work of attacking, validating, and understanding real applications.
Training the World’s Best Offensive AI in the Novee Gym
The Novee Gym continuously evaluates and optimizes Novee’s entire offensive AI system – so it keeps getting better as AI and attacks evolve.
- Proprietary Model + Multi-Model Routing: Novee combines its proprietary offensive model with leading frontier models, intelligently routing each task to the best performer.
- Purpose-Built Offensive Security Harness: Specialized agents, tools, and orchestration work together to discover, exploit, and validate complex vulnerabilities.
- Continuous Benchmarking + Optimization: The Novee Gym continuously evaluates the full offensive AI system against real applications to improve overall performance.
Our eight questions above are designed to help you determine whether an AI penetration testing platform can actually replicate attacker behavior, or whether it is simply automating existing scanning workflows.
Here’s how we meet the criteria:
1: “Do you own your model and harness, or are you orchestrating third-party LLMs?”
Novee is the only AI pentester that owns the full offensive AI stack — both the model and the harness. Most competitors are wrappers: they orchestrate a general-purpose frontier LLM they don’t own, so the harness is the only thing they can improve. Novee owns both, which means two levers to optimize instead of one. We post-train our own proprietary offensive reasoning model on full attack trajectories, and coordinate it with continuously benchmarked frontier models – routing every task to the strongest performer.
Every layer – model, harness, prompts, and orchestration – is trained and optimized inside the Novee Gym, our continuous training environment, where the system is scored on recall, precision, and cost against thousands of real applications and gets stronger every cycle. Each agent is purpose-built for its stage – mapping, planning, exploitation, validation, remediation – running the strongest model for that task
The results are 2x the performance at 6x less cost. Novee achieves this by optimizing for 6 key performance indicators:
- Quality
- Precision
- Recall
- Cost / efficiency
- Speed
- Safety
2: “Do you maintain a persistent, asset-level intelligence layer that compounds across runs and feeds repeated attempts at exploit chains?”
Traditional pentests restart from zero every engagement. Novee builds persistent intelligence about your environment.
The system begins by autonomously mapping the attack surface – domains, APIs, endpoints, workflows, authentication states, and integrations – and stores that understanding in the Asset Intelligence Model (AIM): a living, per-asset intelligence layer that captures the application’s purpose, roles, permissions, workflows, APIs, and business logic. The AIM is shared across all of Novee’s coordinated agents, so new attacks build on previously discovered context and coverage compounds rather than resetting.
3: “Is your system designed to operate continuously and autonomously as environments evolve? Does it provide continuous coverage across my full portfolio, including web, mobile, and desktop applications, without requiring a human in the loop on every test”
Yes, the system operates continuously and autonomously across your entire environment, and can be triggered on any delta changes via CI/CD integration. Humans control scoping and approve safety guardrails, but are not required to be “in the loop” of the tests; meaning they can focus on strategic testing, prioritization, and the highest-impact risks. The core offensive workflow runs autonomously and continuously across your full portfolio – web and mobile applications alike – extending coverage to the assets a quarterly engagement would never reach.
A central orchestrator coordinates six specialized agent ro
les: Mappers (continuously map the attack surface), Analyzers (build the AIM), Planners (generate application-specific test cases mapped to OWASP WSTG and AITG), Hunters (carry out exploit attempts as changes occur), Validators (prove exploitability), and Fixers (deliver tailored remediation). Together they simulate the workflow of a human pentester, except they run continuously and explore different attack paths in parallel.
4: “Can your system autonomously find multi-step vulnerabilities in-production, escalating severity across multiple endpoints?”
Novee’s reasoning model is specifically designed to discover and execute multi-step exploit chains, which combine small weaknesses across workflows, integrations, and access boundaries. We specialize in uncovering business logic flaws, stateful authorization bugs, chained injection vulnerabilities, and cross-system attack paths.
These are the classes of vulnerabilities most frequently missed by scanners, but often discovered by elite human pentesters.
5: “Do you generate a working proof-of-concept for each critical finding, and how is it validated before it reaches my team?”
Novee is built for zero false positives by design. Every potential finding passes through three independent validation agents:
- Agent 1 exploits the vulnerability.
- Agent 2 re-exploits it blind, with no context from Agent 1.
- Agent 3 validates independently.
Where possible, validation is deterministic – not LLM-based – confirming exploitability with certainty rather than inference. If any stage fails, the finding is never reported, so security teams receive a small set of high-confidence findings rather than thousands of alerts requiring manual triage.
6. “Can you begin testing without my crown jewels, and get me actionable results fast?”
Novee achieves true black-box pentesting: we don’t ask for your crown jewels up front. Given only a domain, the system autonomously performs infrastructure discovery, endpoint enumeration, API mapping, workflow reconstruction, and attack surface expansion.
Because deployment requires no integrations or source code access, organizations can start testing immediately and see meaningful findings within hours. As additional access is optionally granted (gray-box or white-box), Novee can add additional areas of focus to testing results, but value is delivered immediately from the external attack surface.
7. “Are remediation steps tailored to my architecture? And do you automatically retest fixes?”
Because Novee both discovers and exploits vulnerabilities, it understands exactly how each issue manifests in the application, and generates personalized remediation guidance specific to your WAF, backend, and codebase, not generic OWASP references.
Novee’s Agentic Fix capability takes this further: it turns each validated finding into a tailored, code-level fix – routed to your preferred AI coding agent or straight into your CI/CD workflow – rather than leaving your engineers to interpret a report. Once the fix is deployed, the system automatically retests the attack path to confirm the vulnerability has been eliminated and that the change didn’t introduce new risk. This is closed-loop remediation: every finding moves from discovery to verified fix in one continuous workflow.
8. “Is your platform safe to continuously run in production – does it get privileged access without guardrails?”
Because Novee owns the full offensive AI stack, safety is a design constraint from the start, not a layer bolted on at the end. Before any assessment touches your environment, the AI stack is tested against tripwire scenarios: specific actions the agent must never take, which we confirm it stops at rather than crossing.
Novee then enforces safety in two layers. Hard guardrails are deterministic controls that live outside the language models, in an intercepting proxy every agent request passes through Because they sit outside the models, a lateral-thinking model can’t reason its way around them. Soft guardrails steer the agent’s judgment through the models: baseline safety system prompts on every run, per-assessment natural-language instructions (e.g. “focus on the RBAC capabilities”). A separate Gatekeeper agent that watches what the testing agent intends to do and judges whether each action is acceptable before it happens.
Every test also begins with a preliminary report, showing you exactly which components will be tested and how. Together, these protections let Novee operate continuously in production while the boundaries stay firmly in your hands.
How Novee Discovers Novel Vulnerabilities and Delivers Instant Remediation Guidance
The below examples – one research-focused, the other based on a real-world customer environment – show exactly how Novee operates, and how we achieve our mission: uncovering novel vulnerabilities and delivering precise, personalized fixes tailored to your environment.
Research: Discovering 16 New 0-Day Vulnerabilities in PDF Engines
Novee’s research team demonstrated the platform’s depth by discovering 16 previously unknown zero-day vulnerabilities across widely used PDF engines, using a 3-phased approach.
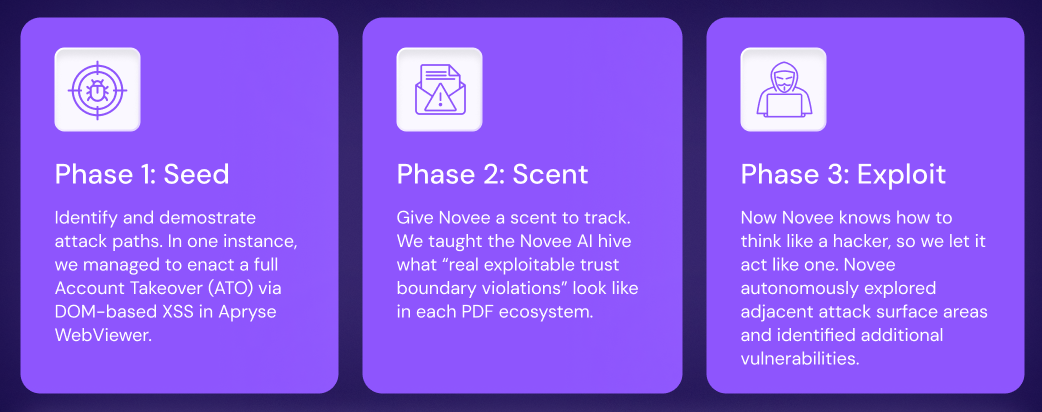
As a result, the Novee AI discovered 13 new exploitable vulnerabilities, in addition to the 3 found by our researchers.
Faced with dynamic code paths and real trigger conditions, most tools would stop trying to find an exploit, or at best, guess where one might be found.
Novee AI doesn’t give up, and it doesn’t need to guess, because behind our team of human researchers is a hive of AI agents, specialized and designed to replicate their intuition, experience, and persistence.
—
Customer Case Study: UiPath
“Novee adapted to our multi-tenant SaaS product within days and now gives us ongoing validation that our tenant isolation holds up against real attacker techniques. That level of assurance is what our customers expect of us, and it’s exactly what we give them through this partnership.”
— Scott Roberts, CISO, UiPath
UiPath is the world’s leading business orchestration and automation platform, trusted by thousands of customers across heavily regulated industries to run mission-critical workloads and hold their most sensitive data. It ships constantly – over 500 releases to its cloud platform in a single year – so for CISO Scott Roberts, point-in-time testing was a non-starter. He needed continuous proof that tenant isolation in UiPath’s multi-tenant SaaS environment would hold up against real attacker techniques.
What set Novee apart was that it learned how UiPath actually works before testing it – mapping the multi-tenant architecture and the way customers build workflows on the platform, then reflecting that environment within days. For Scott’s team, the shift to continuous, attacker-level validation meant:
Vulnerabilities surfaced inside UiPath’s core business logic – not generic dependency lists
Exploitability proven and chained the way a real attacker would, not theorized
Continuous validation between audit cycles like AIUC-1, keeping pace with release velocity
Novee runs continuously as an extended part of the UiPath security team – proving, not assuming, that tenant isolation holds.
—
Data Proof: Purpose-Trained AI Models vs. Frontier
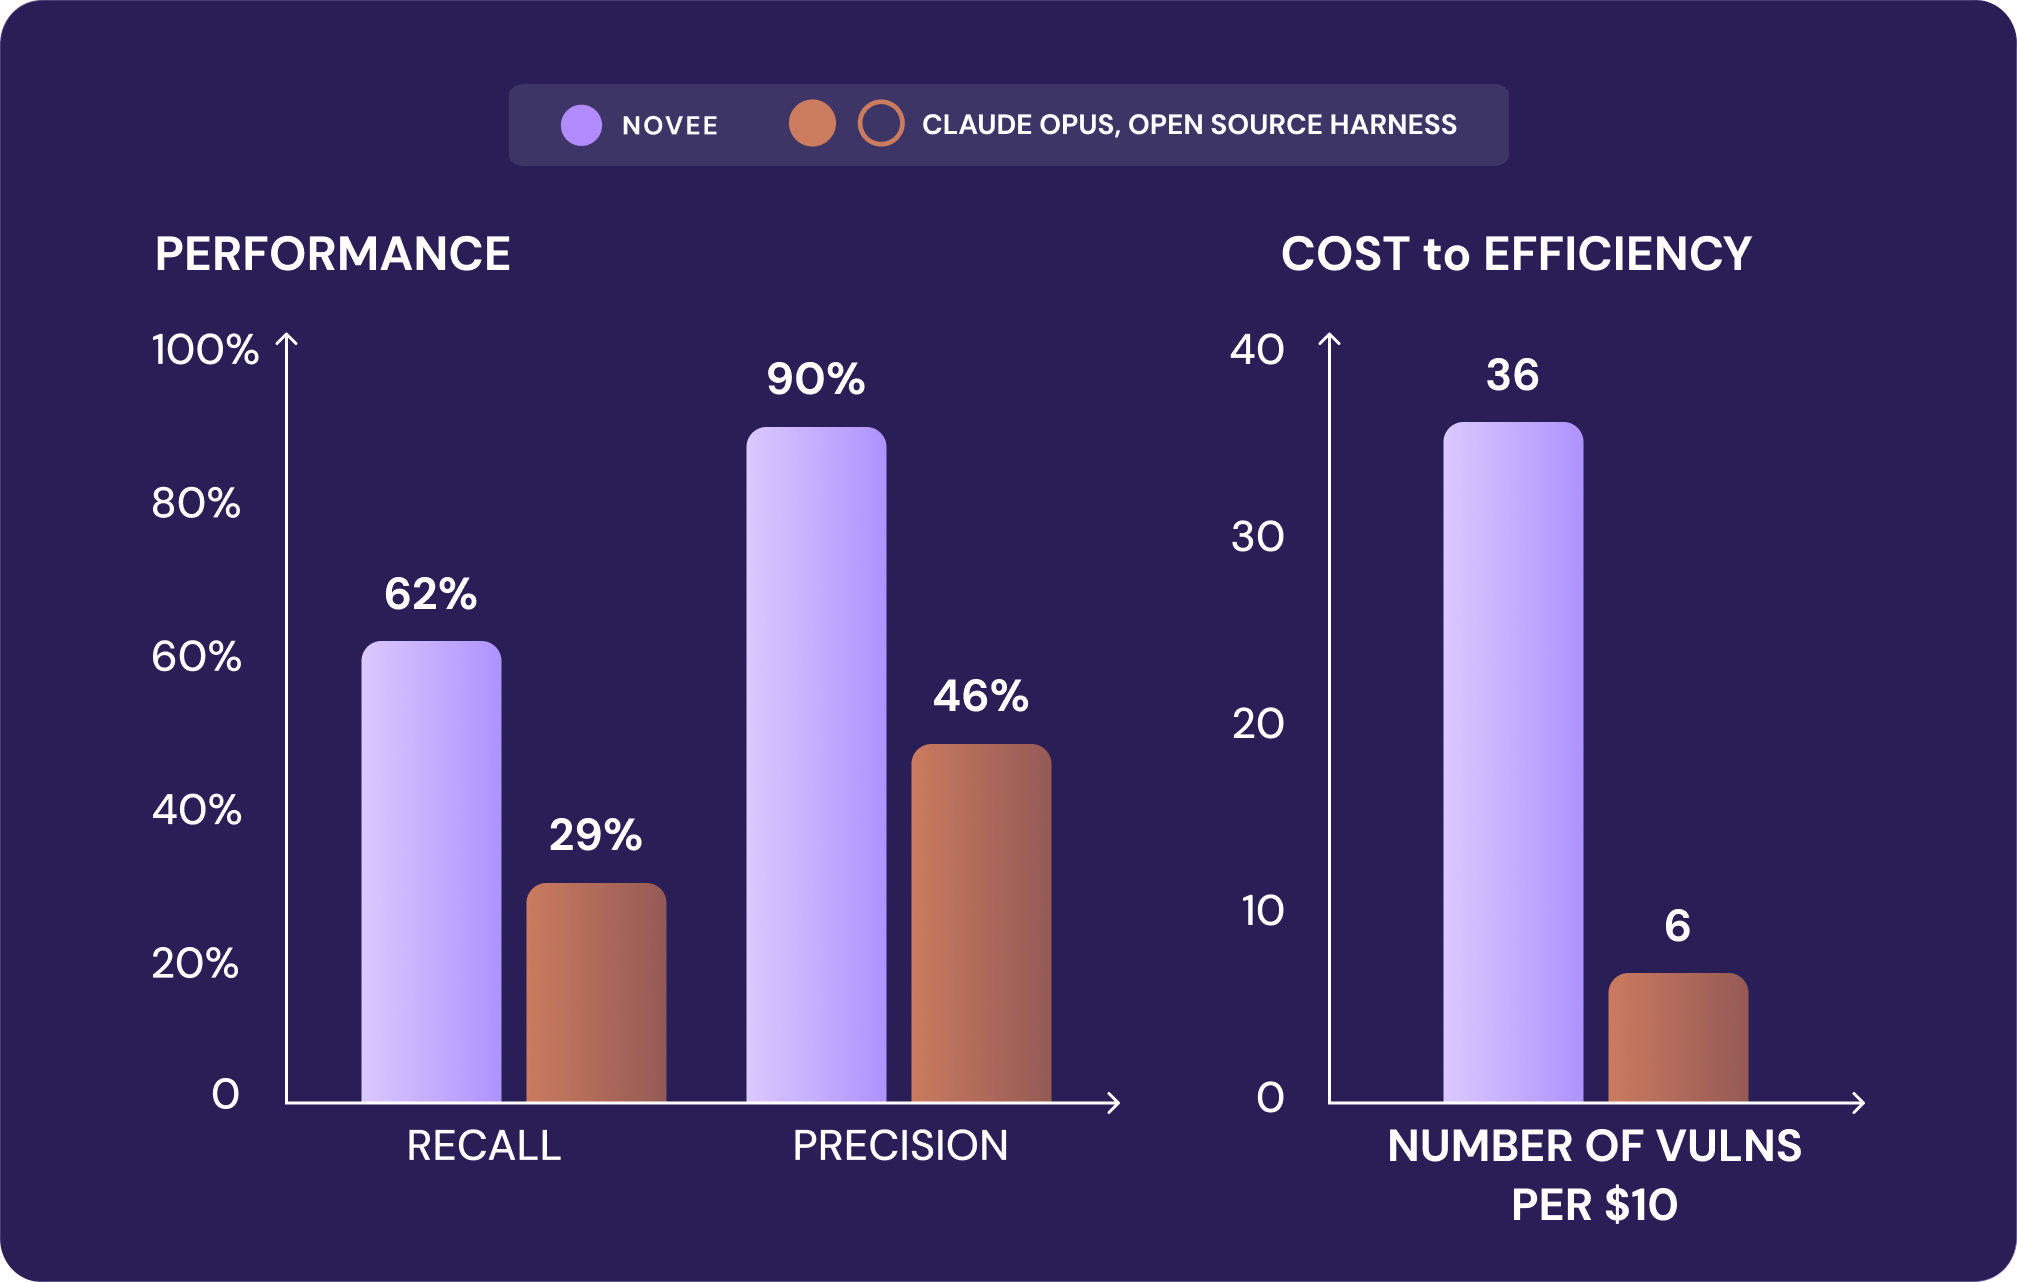
We benchmarked Novee on real penetration testing tasks – applications that look and behave like production targets, with documented and zero-day vulnerabilities – against an open-source harness running Anthropic’s Claude Opus model at maximum performance. Novee came out ahead on both recall (62% vs. 29%) and precision (90% vs. 46%): it surfaced close to twice as many real vulnerabilities while keeping nearly twice the precision, so far fewer findings were noise.
In a separate benchmark focused on cost efficiency, Novee found 6x more vulnerabilities per dollar than the same open-source harness running Claude Opus. Frontier models are strong, but they aren’t trained on the specific challenge of live adversarial exploitation. Novee’s advantage isn’t any single model – it’s owning and training the full offensive AI stack in the Novee Gym, where a proprietary model post-trained for offensive reasoning is routed alongside frontier models and the whole system is optimized for quality, precision, recall, cost/efficiency, speed, and safety. That’s the difference a full stack, built and trained for offensive security, makes.
—
How Novee Can Help You
Novee was built by national-level offensive, defensive, and AI security leaders who distilled elite attacker tradecraft into a proprietary offensive AI model – then trained the full stack, model and harness, in the Novee Gym so it gets stronger every cycle. Designed to think like a real adversary and go to work alongside your team, Novee discovers, maps, and exploits novel vulnerabilities across web and mobile applications with context and precision, scaling your pentesting team across your entire portfolio.
Novee clearly answers the question: Can someone break into your system right now?
Get a demo of the Novee platform, and be up and running in days with a continuous, validated report of novel vulnerabilities across your platform. And the guidance for how to fix them.